Technology-Centric Kimi Encounters Hurdles in Global Expansion
 10/29 2026
 536
By Tian Yu
Edited by Shen Xiao
On the morning of October 24, Kimi unveiled its latest iteration, the K3.1 Pro model. The official announcement emphasized two key enhancements: the model's capabilities now rank among the elite in the flagship category, and API pricing has been slashed by roughly one-third compared to its predecessor.
Nonetheless, post-launch, Kimi encountered backlash regarding its cost-efficiency due to the swift Token consumption rate.
From a pricing standpoint, the official API rates have indeed seen a reduction.
The input cost for K3.1 Pro dropped from 20 yuan to 13 yuan per million Tokens, while the output cost decreased from 100 yuan to 68 yuan. However, these savings were not equally felt by C-end users and international developers.
Some users undertook the classic task of generating an image of a "pelican riding a bicycle," which took 1 hour and 47 minutes, consuming 87% of the 5-hour quota and 16% of the weekly quota. A developer noted that sending a simple "Hello" message consumed 42,000 Tokens.
On October 26, Kimi issued an apology and compensation statement, acknowledging, "The responsibility lies with us; we should have addressed this sooner." The company proposed two solutions: resetting and compensating quotas for active subscription members and optimizing model configurations to minimize unnecessary sub-agent calls and output length.
The statement admitted that the model's underlying invocation mechanism was not adequately controlled.
Previously, users had a straightforward understanding of model pricing: costs were calculated based on the number of Tokens output, multiplied by the unit price.
However, a single request may now encompass long-context reading, background reasoning, task decomposition, tool invocation, sub-agent collaboration, and multi-round self-correction.
A user might submit just one sentence, but the model could execute a series of actions in the background. As long as each task consumes more Tokens, even with decreased API prices, the user's final cost may still rise.
K3.1 Pro is officially touted as the "most capable 3-trillion-parameter model to date," supporting 1 million Token contexts and tailored for long-form programming, 3D creation, and financial research. These advantageous scenarios are prone to triggering tasks involving long contexts and multi-agent invocations.
Independent research institution Artificial Analysis evaluated K3.1 Pro, awarding it an intelligence score of 55, ranking fourth globally and first among open-source models, an 11-point improvement over K3. According to this ranking, if the model weights are released as planned, it could become the highest-scoring open-weight model on the list.
These accomplishments indicate that Kimi has indeed made a significant leap in capabilities.
However, there remains a disparity between foundational model performance and the actual user experience for ordinary users.
To assess K3.1 Pro's performance in daily tasks, we utilized a Pro subscription account to test multiple creative tasks consecutively through the Kimi desktop application.
The focus was not on the impressiveness of a single response but on four aspects: initial generation effectiveness, modification process, final completion, and Token consumption.
As of the afternoon of October 27, the account's total monthly usage stood at 27.03%, with five test tasks consuming approximately 25.48% combined.
The "pelican riding a bicycle" task is a classic benchmark that emerges after nearly every new model release. It originated from tech blogger Simon Willison, who posed a simple challenge: "Generate an SVG of a pelican riding a bicycle."
SVG requires describing graphics with code, so the model must comprehend the structure of pelicans and bicycles while managing spatial relationships between wheels, frames, bird legs, and pedals. Why did Simon focus on "pelican riding a bicycle"? Partly because he liked it, and partly because similar online materials were scarce at the time, making it difficult for models to directly replicate images from training data.
As model capabilities advanced, this test gradually became a "ritual" for new model releases. This time, we upgraded the task to a short video, observing not only structure and aesthetics but also whether the riding motion appeared natural and the footage was coherent.
We requested a smiling pelican riding a bicycle along the coastline at sunset, with waves continuously crashing against the shore.
The task was accomplished in one attempt without further modifications, yielding excellent results. The pelican's expression was vivid, its feathers fluttering in the wind; the waves crashed naturally, and the overall style was warm.
The quota breakdown revealed that the K3.1 Pro model entry consumed 0.13%, while the Plugin entry consumed 5.85%, totaling 5.98%. In other words, without rework, about 97.8% of the consumption came from the Plugin entry.
Next, we tasked it with creating a traditional Suzhou-style courtyard.
The prompt read: "Create a traditional Suzhou-style courtyard with a loquat tree, a wicker armchair and table under the tree, and loquats and teacups on the table."
The initial version was rough, with an overall texture resembling granular building blocks and leaves resembling paper cutouts.
In the second version, we requested replacing the sandbox-style overhead view with a natural perspective and slight depth of field inside the courtyard; using low-angle warm sunlight to enhance the summer atmosphere; replacing the armchair with a recliner, and continuing to refine other details.
This version addressed major issues like perspective, recliner, and palm-leaf fan, but deviations remained in the details. The bamboo grove outside the courtyard was overly simplified, the palm-leaf fan hovered in midair, and the loquats were embedded in the tree roots.
In the third version, we provided a real reference image for it to recreate. With the reference image, the content became richer, but the focus shifted to detail accuracy. The stone pillars protruded, and the stones around the pond resembled foam.
The quota breakdown showed that the initial generation of the Suzhou-style courtyard consumed 1.76%, with subsequent modifications adding another 4.45 percentage points, totaling 6.21% for the entire task, ranking second among the five tests.
The third task was to create a webpage introducing the history of world art. We required a rich representation of key figures and artworks, allowing users to click on portraits or artworks to view related knowledge explanations.
The generated webpage, named "ATHNE | World Art History · Romantic Corridor," created a romantic atmosphere with warm paper tones, deep browns, and soft lighting. Users could filter by cultural track, figure, or artwork, browse by chapter, or search keywords, with animated character effects.
The initial version resembled a curated gallery, featuring only 13 figures and 14 masterpieces, a relatively small number, with Western and Eastern art mixed in the same timeline. When clicking "Next Guide," the text explanation on the right and the artwork on the left were out of sync, with the artwork appearing about three seconds later than the text.
After further optimization, the webpage expanded to 30 figures and 30 works, presented in dual tracks of Western and East Asian art, with a clear chronological structure. Clicking on any portrait, artwork, or timeline node allowed users to read relevant background information. The mobile version also offered smooth browsing, balancing aesthetics and usability.
The art history webpage consumed a total of 4.90% for model entries and 0.02% for Plugin entries, totaling 4.92%.
Next, we replicated tests conducted by two bloggers.
The first was a mechanical keyboard. We asked it to create a high-precision model showcasing the structure of keycaps, switches, positioning plates, PCBs, and housings, while supporting white models, X-ray views, exploded views, and different perspectives.
This generation did not undergo multiple rounds of rework, with the main structure intact and multiple views switching normally. The quota breakdown showed two billing records: 1.09% and 0.37%, totaling 1.46%, the lowest among the five tasks.
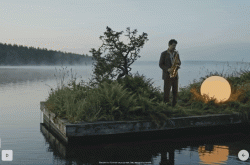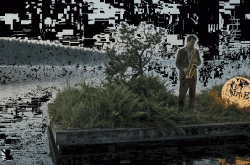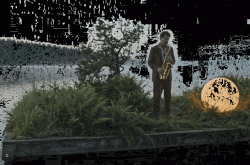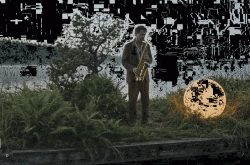
The second task was to recreate "The Peach Blossom Spring."
The initial version leaned toward symbolism, with characters and objects replaced by abstract elements, and an overall texture similar to the first version of the Suzhou-style courtyard. We then provided a reference landscape painting for it to recreate. The second version still failed to capture the spatial changes and narrative layers of the original text, with a noticeable disconnect from the artistic conception of "The Peach Blossom Spring."
We made one final attempt, sending it the original blogger's generated video for as close a recreation as possible. This version showed significant improvement in overall texture and completion. However, several issues remained, such as multiple instances of lighting resembling hollow columns, lacking realistic illumination effects.
This task's quota breakdown showed nine records, accumulating 6.91% in consumption, the highest among the five tests. The final attempt and subsequent adjustments alone consumed 2.88%.
These two cases together show that the mechanical keyboard task was completed in one attempt, consuming only 1.46%, while "The Peach Blossom Spring" underwent multiple rounds of modifications and two rounds of reference material provision, accumulating 6.91% in consumption, nearly five times the former.
Returning to the product itself, the five tasks combined consumed approximately 25.48% of the monthly quota. For complex creative tasks requiring repeated modifications and tool invocations, this consumption level is not low.
"The Peach Blossom Spring" consumed 6.91%, the Suzhou-style courtyard 6.21%, the pelican video 5.98%, the art history webpage 4.92%, and the mechanical keyboard 1.46%. Among these, "The Peach Blossom Spring" and the Suzhou-style courtyard still had room for improvement after multiple attempts.
This set of records reveals three types of costs: costs from repeated modifications, costs from tool invocations, and additional consumption related to reference materials and repeated generations.
Beyond product experience, Kimi's recent overseas promotional controversies have also garnered significant attention.
Kimi engaged an overseas blogger for promotion but required concealing the advertising label, pretending it was the blogger's genuine experience shared voluntarily.
One commenter noted: "Kimi K3.1 Pro is actually a great model and doesn't need fake positive reviews. Yet they chose to take shortcuts, making the entire product launch look terrible."
According to his account, creators participating in the campaign had to submit copy for approval in advance and were instructed not to add the "Paid Partnership" label. The brief also included promotional language comparing Kimi to Claude Opus 5.5.
However, the relevant documents have not been verified, and it remains unclear whether they were issued by Moonshot AI or a third-party agency.
Multiple overseas bloggers also reported being penalized by the X platform after posting content related to Kimi K3.1 Pro.
Review blogger Lumina claimed that they merely tested the model via Arena before its release, without receiving payment or early access from Kimi's official team, yet two of their posts were penalized.
According to these bloggers, some accounts needed to add labels first before restoring their accounts or filing appeals. To regain access, some complied by adding the required labels and then deleted the related posts to avoid fans mistakenly believing they had received promotion fees.
X platform rules mandate that natural content from paid partnerships must display the "Paid Partnership" label. The platform has not publicly explained why these accounts were targeted.
To outsiders, this adds new mysteries to the already controversial product launch. What exactly transpired between paid promotions, independent reviews, and platform moderation?
In June of this year, Jin Wenyi, former President of Globalization at miHoYo, joined Moonshot AI to lead Kimi's overseas expansion and globalization efforts, based overseas in the future. According to reports, Jin left miHoYo in late May and joined Moonshot AI after completing the transition.
At miHoYo, Jin had long overseen overseas distribution and internationalization, participating in building the HoYoverse global brand and guiding products like Genshin Impact and Honkai: Star Rail from China to the global market.
Her joining Kimi indicates that Moonshot AI's challenges have evolved: Kimi no longer just needs to build stronger models but also deliver them to users in different countries and establish a sustainable global business.
Earlier this year, Moonshot AI mentioned in communications with investors that Kimi's overseas revenue had surpassed domestic revenue; after the release of K2.5, global paid users grew fourfold.
Kimi's overseas growth stems from its excellent model performance, but globalizing a Chinese large-scale model company inevitably involves addressing localization, channel management, branding, and trust issues.
-
MG: Divergent Fates in Domestic and Overseas Markets—MG4 Fuels 70% of China Sales, While Leading European Market as China’s Top Exporter
-
![]()
Over 400 Jobs Slashed! Apple Trims Down Traditional Operations as New CEO Sets Sights on AI
-
![]()
Starting from 3149 Yuan! iQOO Neo12 Review: Is Active Cooling a Game-Changer for Gamers?
-
![]()
Is There a New Breakthrough in Robot Training? Google’s Genie 4 Unveiled, Ushering in Real-Time Interaction for World Models
-
![]()
Lei Jun, Despite Wealth Halving, Provides Houses for Xiaomi Staff
-
![]()
This AI Is Learning to Emulate Human Work Patterns: A Real-World Test of Doubao’s Enhanced Work Capabilities
-
Technology-Centric Kimi Encounters Hurdles in Global Expansion
-
Could the Three-Row, All-Electric Flagship SUV BMW iX7, Equipped with an 8K Giant Screen and Produced in North America, Become a Bestseller?