DeepSeek V4 Pro Officially Launches with Price Increase Effective August 17
 10/20 2026
 398

The Agent has become even more powerful, prompting a reassessment of the low-price narrative.

On August 13, DeepSeek officially unveiled the V4 Pro version. Notably, DeepSeek refrained from releasing a blog post or technical report simultaneously, but the API page promptly updated the model version to DeepSeek V4 Pro 0813. Media reports indicate that DeepSeek API will introduce peak-valley pricing starting from August 17. For the official V4 Pro version, the price for standard input will rise from the current 3 yuan to 4.5 yuan during off-peak hours and 9 yuan during peak hours. Similarly, output prices will increase from 6 yuan to 13.5 yuan and 27 yuan, respectively.
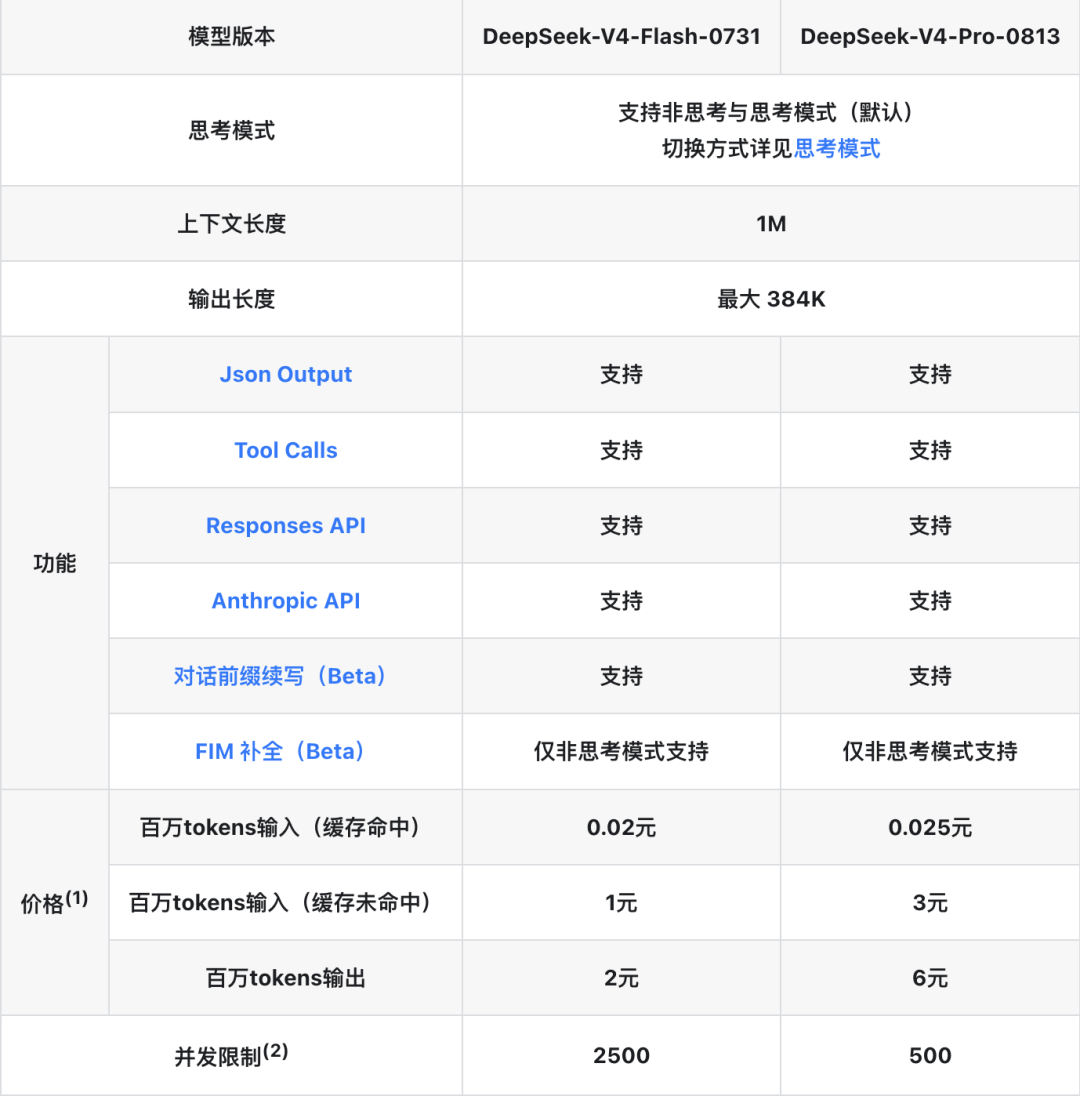
Image Source: DeepSeek Official Website
The journey to the 'official release' of V4 Pro has spanned over seven months. In January, rumors circulated that DeepSeek would introduce the next-generation V4 in February, with a particular emphasis on enhancing Coding capabilities. On April 24, a Preview version of V4 Pro was launched, followed by Flash updates and multiple rounds of Agent optimization, culminating in the official release of V4 Pro on August 13. The most significant improvements are centered around Agent and Coding capabilities.
According to DeepSeek's official test data, the official V4 Pro version saw a substantial increase in its score, rising from 72.1 to 87.9 in the Terminal Task Test (Terminal Bench 2.1), from 12.8 to 62.7 in the Software Engineering Test (DeepSWE), and from 52.7 to 83.3 in the Cybersecurity Task Test (CyberGym). These scores are now on par with, or even surpass, those of Anthropic Claude Fable 5.
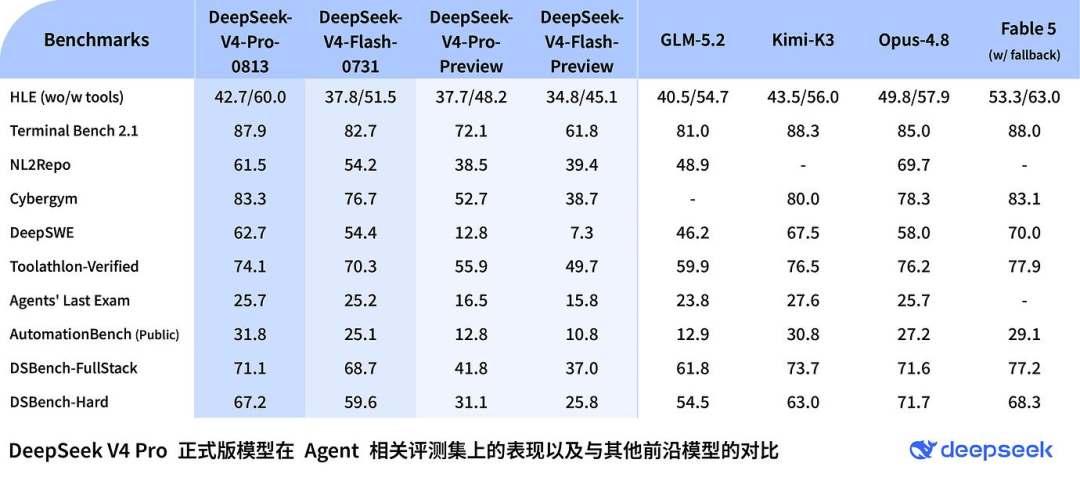
Image Source: DeepSeek Official
From its Preview in April to the official version, V4 Pro has consistently enhanced its Agent capabilities, aligning with the prevailing trend in the entire industry.
01 The Official Version's Highlights Extend Beyond Agent Enhancements
While the official V4 Pro version's most noticeable upgrades are in Agent and Coding capabilities, the improvements go beyond just a few improved test scores.
Firstly, long contexts. The official V4 Pro version continues to support 1 million Token contexts, with a maximum output of 384,000 Tokens, making it more suitable for handling extensive codebases, lengthy documents, and tasks that require sustained attention.
Secondly, tool calls. The official V4 Pro version maintains support for Tool Calls, Responses API, and Anthropic API. Through Anthropic API compatibility, developers can seamlessly integrate DeepSeek into existing tools like Claude Code. Tool Calls provide the necessary interface support for the model to interact with external tools.
Price remains a significant advantage of the official V4 Pro version. Currently, V4 Pro charges 3 yuan for every million Tokens of standard input and 6 yuan for output, while also offering lower cache hit prices. The official version retains long context support, enhances Agent capabilities, and maintains API prices significantly lower than those of leading overseas closed-source models, thus keeping deployment costs in check.
Data from AI evaluation agency Artificial Analysis reveals that the official V4 Pro version scored 53 in the Intelligence Index test, lower than Claude Fable 5's 62. However, the average cost per task for V4 Pro is only $0.06, while Claude Fable 5 costs $3.14, approximately 52 times higher. In the FlappyBench test conducted by AI programming tool company CommandCode, comparing DeepSeek V4 Pro, Kimi K3, Claude Opus 5, and Zhipu GLM 5.2, the official V4 Pro version scored 8 points, lower than the 9-9.5 points of the other models, but with a cost per run of only about $0.0005, significantly lower than the competition. These tests indicate that while V4 Pro's overall capabilities may still lag, its cost advantage is substantial.
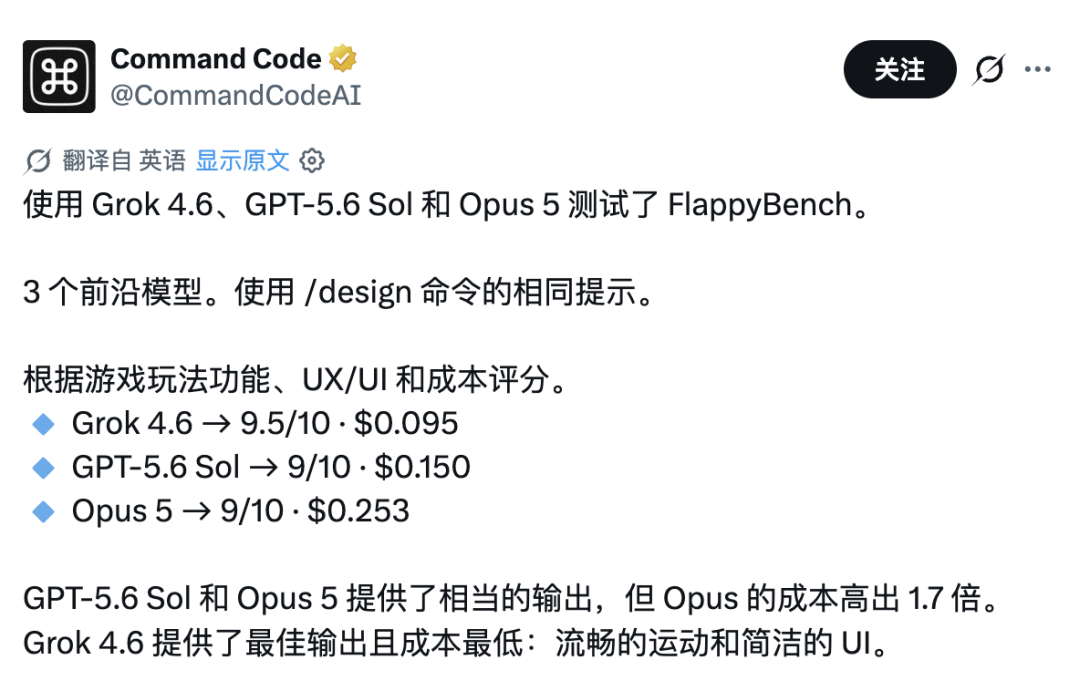
Image Source: Screenshot of an X Post
02 Coding Emerges as a Key Capability of V4 Pro
Among all Agent scenarios, the coding performance of the official V4 Pro version has garnered particular attention from the external community.
When V4 Flash was launched on July 31, DeepSeek specifically disclosed the Code Agent test configuration and utilized its own DeepSeek Harness minimal mode. Harness is responsible for providing terminals, files, and various tools to the model, enabling it to read code, execute commands, check results, and proceed with subsequent modifications. In Agent tests like Terminal Bench, the model and execution framework are evaluated separately because the same model paired with different execution frameworks can produce varying results. According to the official Terminal Bench leaderboard data, using Fable 5 with Claude Code achieves an 83.8% task completion rate, while pairing it with Terminus 2 results in 80.4%.
This focus has extended to developer tools. Currently, DeepSeek officially provides integration methods for tools like Claude Code, Codex, OpenCode, and OpenClaw. In the Claude Code configuration, V4 Pro can serve as the primary model, while V4 Flash is utilized for lighter tasks and Subagents.
This also clarifies the division of labor between the official V4 Pro version and V4 Flash. Both models support 1 million Token contexts, but V4 Flash is more cost-effective and has a higher concurrency limit, while the official V4 Pro version handles more complex tasks.
From specialized Code Agent evaluations, self-developed Harness, to proactive adaptation of development tools like Claude Code, Coding has emerged as a key usage scenario for the official V4 Pro version.
03 Narrowing the Gap with Leading Models: The Persistence of a Low-Price Advantage
With enhanced Agent capabilities, the gap between the official V4 Pro version and leading models is narrowing. Although this update does not 'fully catch up with Claude Fable 5,' in certain tasks such as terminal operations, tool calls, and Agent execution, the two models are now on par in terms of capability.
Meanwhile, leading models are also undergoing frequent updates, and price has become an increasingly critical competitive dimension. Anthropic Fable 5's API pricing is $10 per million Tokens for input and $50 for output; Zhipu GLM-5.2 is approximately $1.4 and $4.4; Kimi K3, released in July, costs 20 yuan for input and 100 yuan for output; Qwen3.8-Max, launched in August, costs 12 yuan for input and 36 yuan for output, while Grok 4.6 costs $2 for input and $6 for output.
In comparison, V4 Pro API currently charges 3 yuan for every million Tokens of standard input and 6 yuan for output, maintaining the same prices as the V4 Pro Preview and remaining significantly lower than this new batch of flagship models. However, the price lead is diminishing. Moreover, DeepSeek previously announced on its API page plans to raise service prices overall in the near future, indicating a substantial expected increase. The extent to which V4 Pro will retain its price advantage after the official price hike will directly impact its competitiveness.
From its Preview in April to the official version in August, the upgrade path for V4 Pro has gradually become clear: determining parameter scale and million-Token context support during the V4 Pro Preview phase, followed by continuous enhancements to Agent and Coding capabilities, the addition of Harness and Agent tool integration. By the official V4 Pro version, Agent has become the most evident upgrade direction for this generation of models. After the price adjustment on August 17, V4 Pro will still retain a significant price advantage over overseas models, but the price gap with some domestic models will further narrow. The ultimate position that the official V4 Pro version will occupy remains to be seen.
(The images and public data materials in this article are sourced from the internet and public industry platforms. If there is any infringement, please contact us promptly for corrections.)
-
![]()
Self-Developed Chip Valued at 10 Billion Yuan: Can Li Auto’s Second Growth Curve Succeed?
-
![]()
The Year of High-Intensity Action: What Is Ant Group Betting On?
-
![]()
DeepSeek V4 Pro Officially Launches with Price Increase Effective August 17
-
![]()
Keynote Speaker | Li Yanming, Volcano Engine’s Senior Enterprise Solution Expert, Confirmed for WAIE (10th) 2026 AI Industry Conference & AI Agent Industry Application Conference
-
![]()
Nvidia Brings in Wall Street, Potentially Revolutionizing Valuation Logic for Computing Power
-
![]()
High-Profile Guest | Qiao Yuchuan, Director of Embodied Intelligence Solutions at SenseTime, Confirmed to Attend WAIE (10th) 2026 AI Industry Conference & AI Agent Industry Application Conference
-
![]()
Conant Optical Claims Spot in Alibaba’s Qianwen AI Glasses Core Optical Supply Chain!
-
![]()
Breaking Away from Integrated Assembly: What’s the Wager of This Domestic FTIR ‘Little Giant’?